rizzo-flow hedgehog mascot

rizzo-flow

Decisioni tipizzate da un LLM, senza generare un token Typed decisions from an LLM, without generating a token

La versione open e locale di Jev. Dai uno state, fai le tue domande: torna un sì/no, una classe, uno score o un numero, con le probabilità. Sul tuo computer. The open, local take on Jev. Give it a state, ask your questions: get back a yes/no, a class, a score or a number, with probabilities. On your own machine.

100% LOCAL 0 TOKEN GENERATI0 GENERATED TOKENS API COMPATIBILE JEVJEV-COMPATIBLE API OPEN SOURCE · APACHE-2.0
~50 msper decisione · 8 bit, RTX 5060 Tiper decision · 8 bit, RTX 5060 Ti
4B · 1.7Bparametriparameters
1Mtoken di contesto nativotokens of native context
~5 GBRAM · 8 bit

GPU Apple, NVIDIA, AMD, Intel o sola CPU · llama.cpp · nessuna chiave API, nessuna telemetria Apple, NVIDIA, AMD, Intel GPUs or CPU only · llama.cpp · no API key, no telemetry
Un dato entra, una decisione esceData goes in, a decision comes out

Scegli un esempio e il tipo di risposta, poi dallo in pasto al riccio. Pick an example and an answer type, then feed it to the hedgehog.

state
domandaquestion
0 ms

Risposte e tempi reali, registrati da Spark-X2.5-4B Q8_0 con llama.cpp su una RTX 5060 Ti (mediana di 5 chiamate a caldo, prompt v3). Nessuna risposta è stata scelta o corretta a mano. Il viaggio dei dati è rallentato per farsi vedere; il riccio "pensa" davvero per quei millisecondi. Real answers and timings, recorded from Spark-X2.5-4B Q8_0 with llama.cpp on an RTX 5060 Ti (median of 5 warm calls, prompt v3). No answer was picked or fixed by hand. The data's journey is slowed down so you can see it; the hedgehog really "thinks" for that many milliseconds.

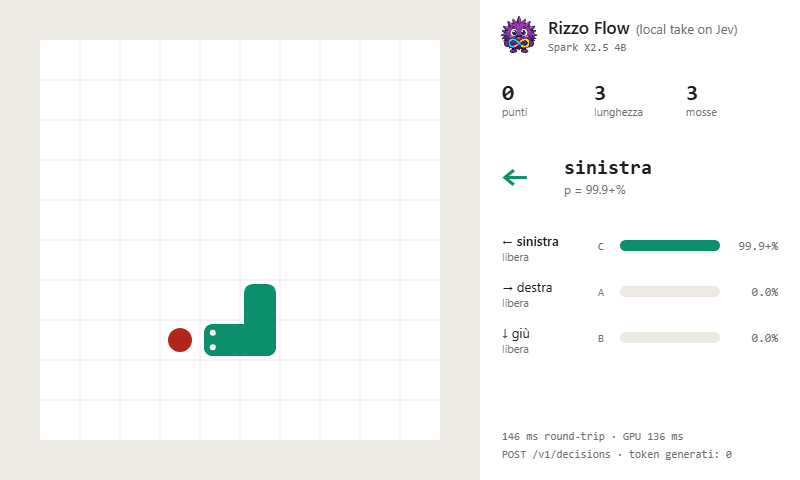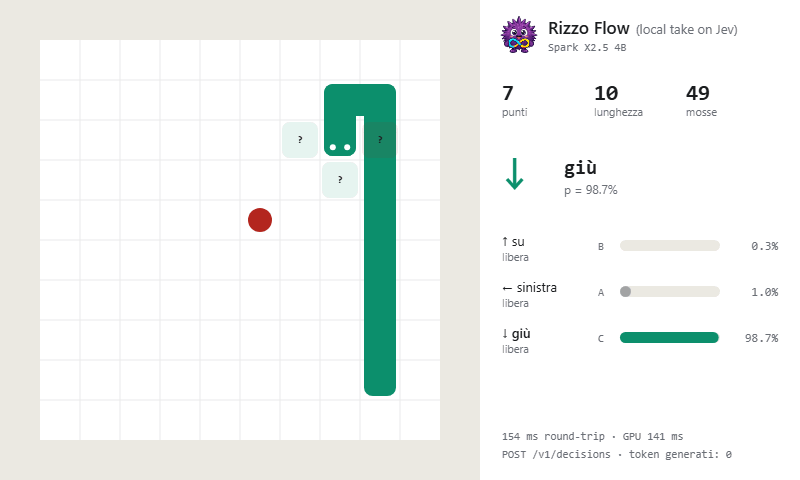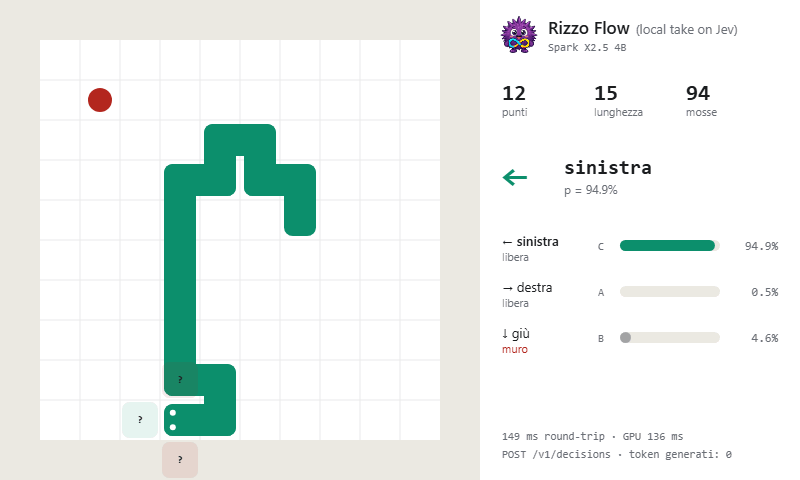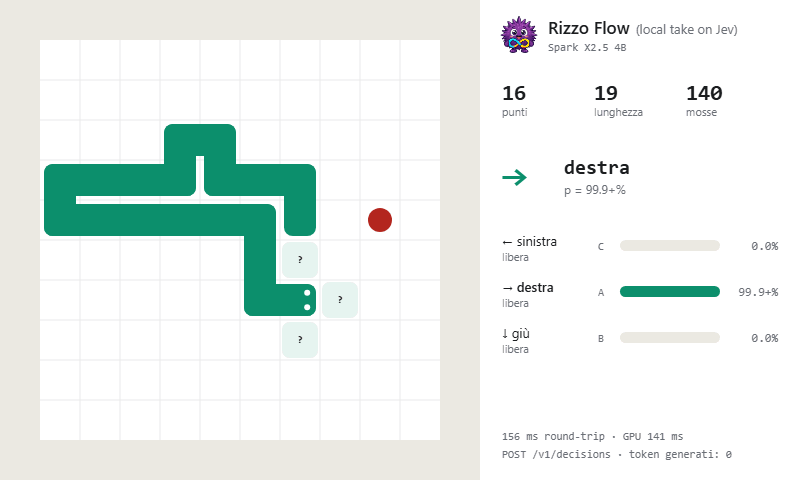
Abbastanza veloce da giocare a SnakeFast enough to play Snake

Ogni mossa è una decisione del modello: una POST /v1/decisions, zero token generati. Every move is one model decision: one POST /v1/decisions, zero generated tokens.

Una partita a Snake giocata da rizzo-flow: a ogni mossa le barre mostrano la probabilità di ogni direzione, circa 150 ms a decisione

Registrazione a velocità reale, non accelerata: 140 mosse in 25,6 s (≈ 5,5 al secondo), circa 150 ms a decisione andata e ritorno. Spark-X2.5-4B a 8 bit su una RTX 5060 Ti, registrata con il precedente runtime MLX (con llama.cpp ogni decisione è ~1,8× più veloce). È una sola partita, non un benchmark; la demo è inclusa nel backend su /snake. Recorded at real speed, not sped up: 140 moves in 25.6 s (≈ 5.5 per second), about 150 ms per decision round trip. Spark-X2.5-4B at 8 bit on an RTX 5060 Ti, recorded with the earlier MLX runtime (llama.cpp is ~1.8× faster per decision). One game, not a benchmark; the demo ships with the backend at /snake.

Come funzionaHow it works

La decisione è già nel modello dopo un solo passaggio: basta leggerla. The decision is already in the model after a single pass: you just read it.

1

📥 State

Testo o JSON: un ticket, un CV, un log.Text or JSON: a ticket, a CV, a log.

2

🧠 Un solo prefillOne prefill

Lo state si elabora una volta; la cache si riusa per ogni domanda.The state is processed once; its cache is reused for every question.

3

🔤 Lettere, non testoLetters, not text

Ogni risposta possibile è una lettera. Si leggono solo quei logit.Every possible answer is a letter. Only those logits are read.

4

📦 JSON tipizzatoTyped JSON

Valore + probabilità. Niente parsing, niente errori di tipo.Value + probabilities. No parsing, no type errors.

La stessa API di JevThe same API as Jev

Stessa richiesta, stessa risposta: cambi solo l'URL. E la risposta dichiara sempre il modello locale. Same request, same response: you only change the URL. And the response always names the local model.

POST http://127.0.0.1:8017/v1/systemone { "state": "My payouts have been failing for 3 days.", "model": "rizzo-latest", "questions": { "is_urgent": { "type": "noul", "instructions": "Does this convey urgency?" }, "team": { "type": "choice", "instructions": "Which team should handle this?", "criteria": { "billing": "Payments", "technical": "Bugs" } } } }
200 OK · 0 generated tokens { "model": "rizzo-spark-x2.5-4b-q8", "answers": { "is_urgent": { "type": "noul", "noul": 0.99 }, "team": { "type": "choice", "choice": "billing", "probabilities": { "billing": 0.99, "technical": 0.01 }, "confidence": 0.98 } }, "usage": { "input_tokens": 212, "output_tokens": 0 } }

Forma della risposta; i valori qui sono illustrativi. Shape of the response; the values here are illustrative.

Giudizio da LLM, comportamento da funzioneLLM judgment, function behaviour

Per classificare, instradare, dare un punteggio, verificare. Dentro il tuo codice.To classify, route, score, verify. Inside your code.

🔒

Tutto in localeFully local

Pesi open sul tuo Mac o sulla tua GPU NVIDIA. Nessun dato esce, nessuna chiave API.Open weights on your Mac or your NVIDIA GPU. No data leaves, no API key.

⚡

Zero token generatiZero generated tokens

Un passaggio, nessun ciclo di generazione: circa 50 ms a decisione su una RTX 5060 Ti a 8 bit.One pass, no decoding loop: about 50 ms per decision on an RTX 5060 Ti at 8 bit.

🧮

Quattro primitiveFour primitives

boolean, choice, score, numeric. Fino a 26 opzioni per domanda.boolean, choice, score, numeric. Up to 26 options per question.

🧵

Tante domande, un solo stateMany questions, one state

21 domande su uno state da ~2.000 token: 1,0 s con il prefill condiviso, 8,1 s senza (RTX 5060 Ti, 8 bit).21 questions on a ~2,000-token state: 1.0 s with the shared prefill, 8.1 s without (RTX 5060 Ti, 8 bit).

🤷

Sa dire "non lo so"It can say "I don't know"

Astensione e fuori scala integrati: il valore diventa null, con uno status.Built-in abstention and out-of-range: the value becomes null, with a status.

📚

Contesto da 1M1M context

Attenzione ibrida: ~36 KiB di cache per token. Il limite lo scegli tu con --ctx.Hybrid attention: ~36 KiB of cache per token. You pick the limit with --ctx.

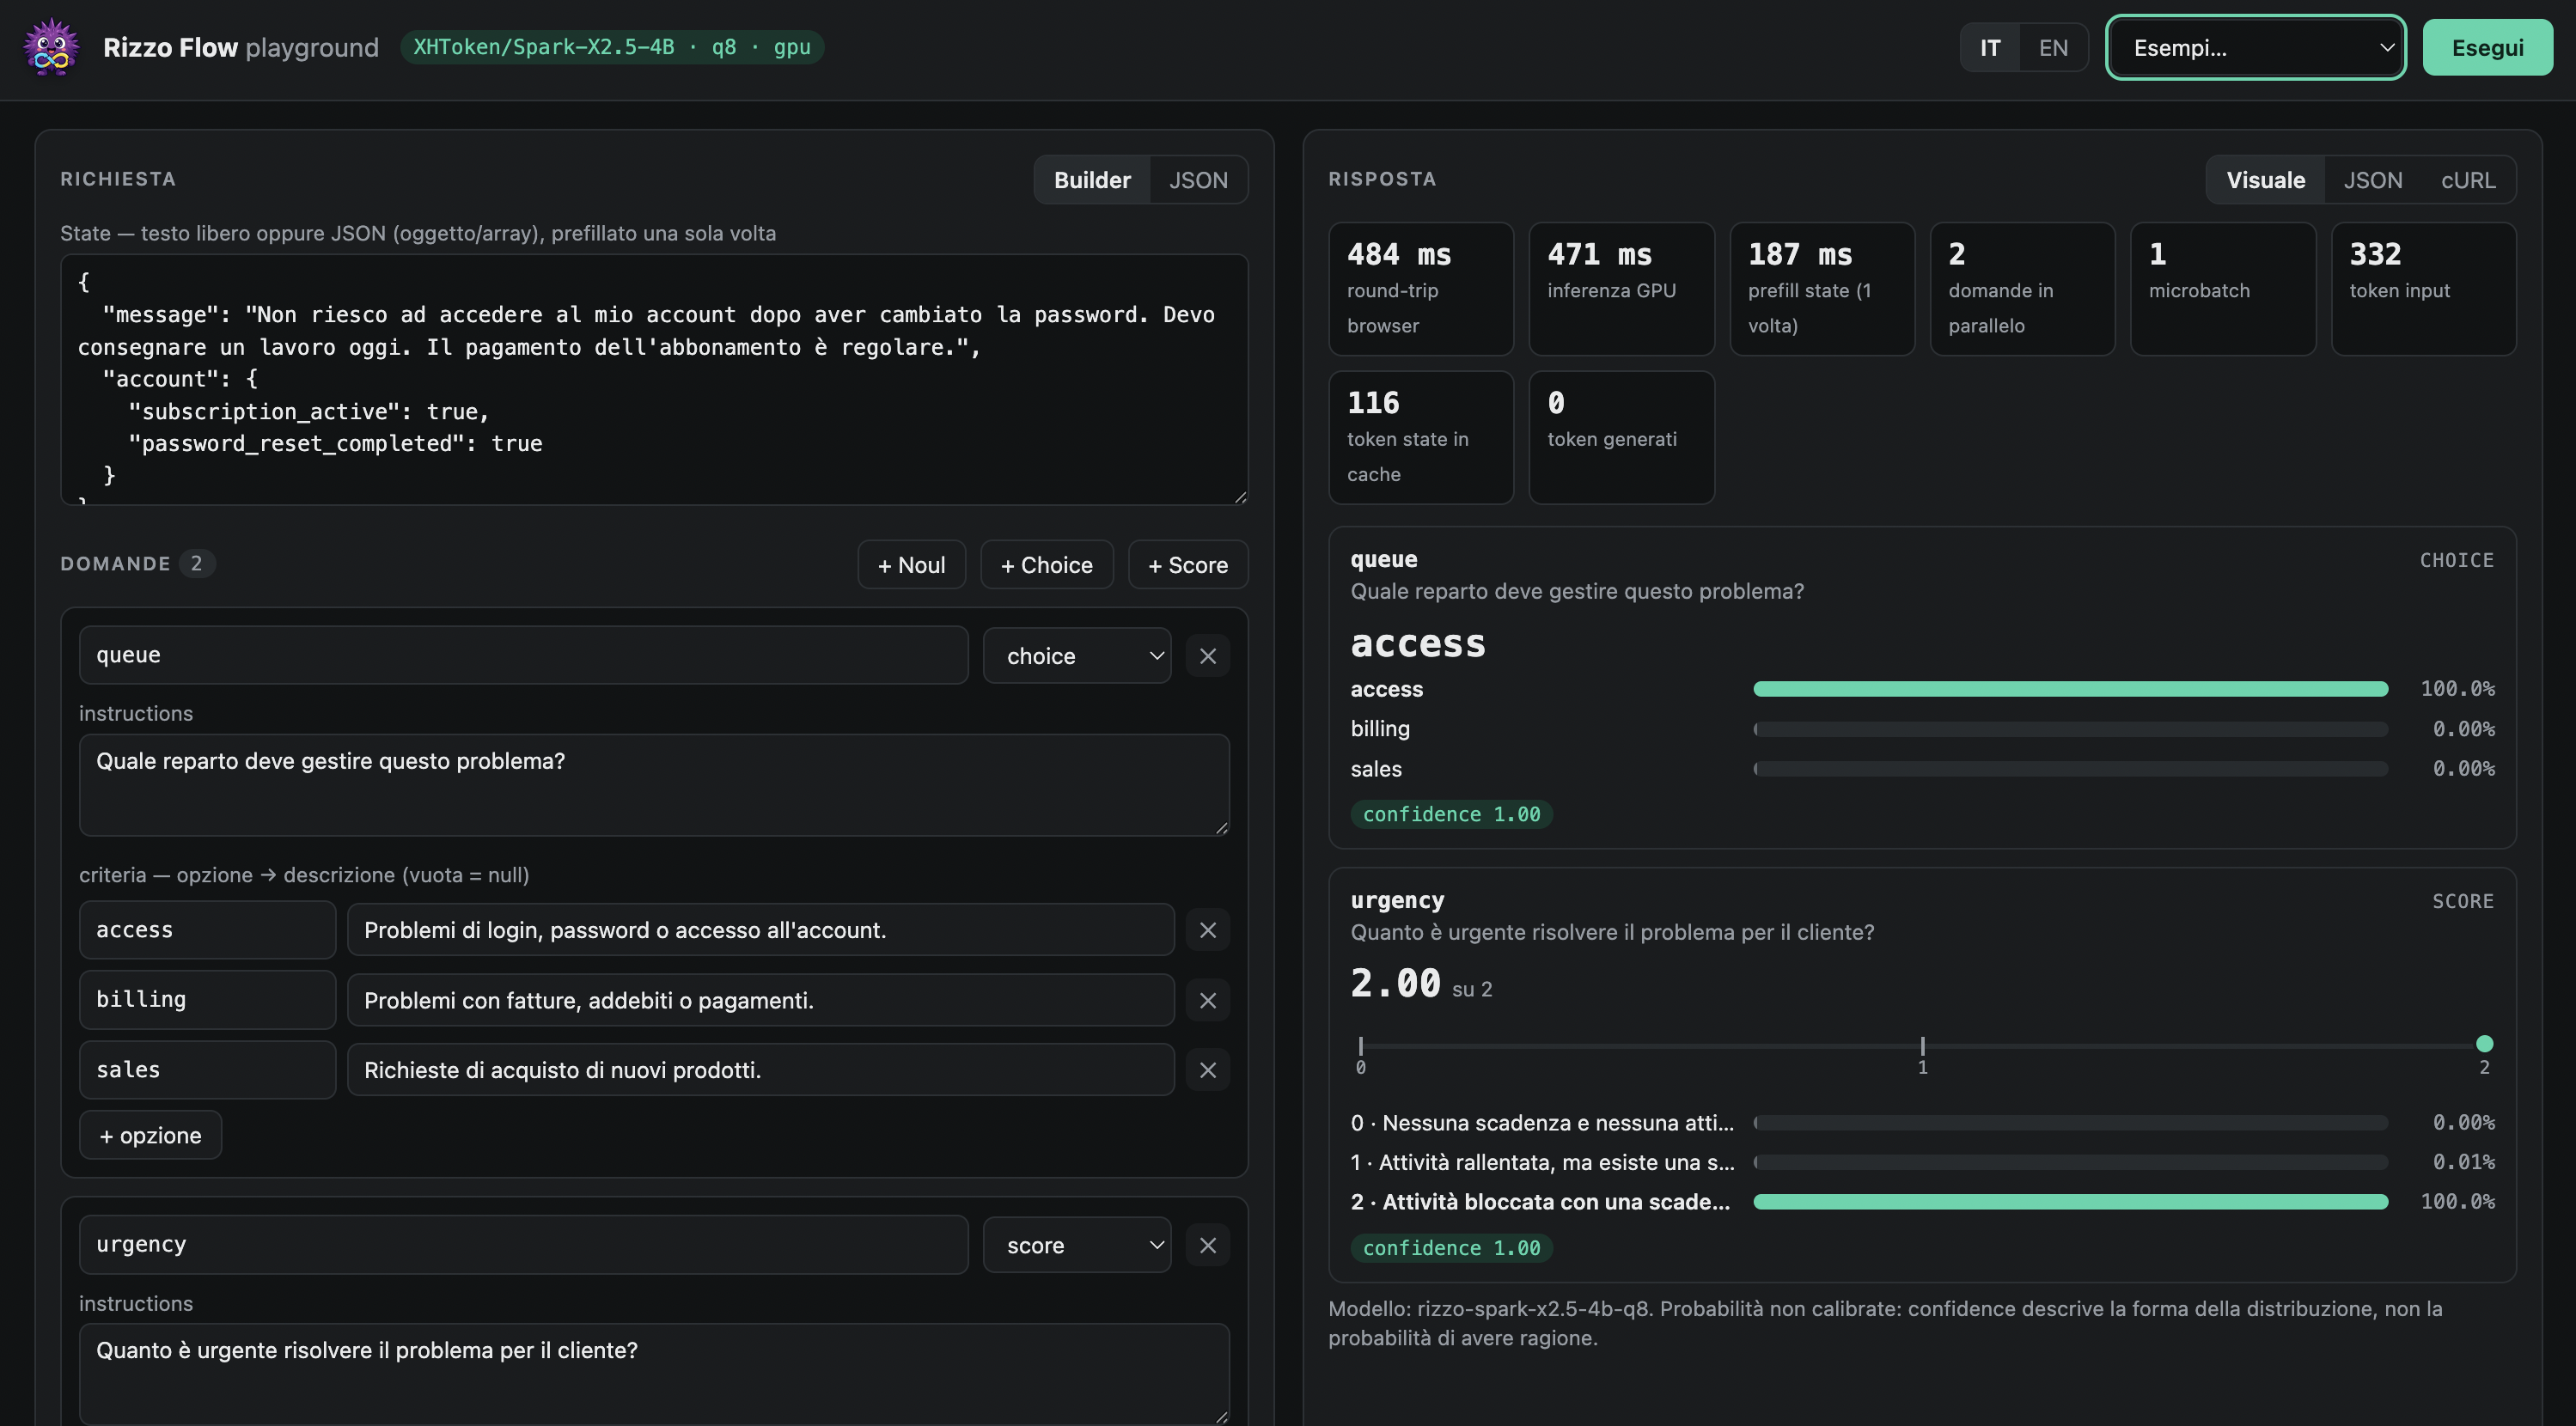
Il playground di rizzo-flow: state e domande a sinistra, risposte con barre di probabilità e tempi a destra

Il playground incluso nel backend, in italiano e in inglese. The playground that ships with the backend, in Italian and English.

Come si confrontaHow it compares

Senza sconti: dove siamo avanti e dove no.No sugar-coating: where we lead and where we don't.

rizzo-flowJev (TypeSafe)SemIf
Dove giraWhere it runsIn locale · Metal, CUDA, Vulkan (AMD, Intel), ROCm, SYCL, CPULocal · Metal, CUDA, Vulkan (AMD, Intel), ROCm, SYCL, CPUServizio cloudHosted serviceIn locale · CUDA, MLXLocal · CUDA, MLX
Pesi openOpen weights✓ Spark-X2.5✗✓ Qwen3.5
API HTTP stile JevJev-style HTTP API✓l'originalethe original✗ CLI
Primitiva numericaNumeric primitive✓✗✗
Opzioni per domandaOptions per question2625516
Probabilità calibrateCalibrated probabilitiesle calibri tuyou calibrate✓ dichiarateclaimed✗
Contesto in inputInput context1M token1M tokens32k262k
Qualità su authored144Quality on authored1440.845—0.819
Qualità su perturbations108Quality on perturbations1080.946—0.766

Progetto indipendente, non affiliato a TypeSafe. Independent project, not affiliated with TypeSafe.

Quickstart

Mac, Windows o Linux, con GPU Apple, NVIDIA, AMD, Intel o senza GPU. Python 3.11+ e uv. Quattro comandi, niente da compilare: rizzo download scarica il runtime llama.cpp adatto alla macchina. *Verificato dal progetto su Windows + NVIDIA; segnalazioni pubbliche includono Mac M3 Pro/Metal e AMD/Intel con Vulkan. Dettagli dei test hardware.Mac, Windows or Linux, with an Apple, NVIDIA, AMD or Intel GPU, or none. Python 3.11+ and uv. Four commands, nothing to compile: rizzo download fetches the llama.cpp runtime for your machine. *Verified by the project on Windows + NVIDIA; public reports include Mac M3 Pro/Metal and AMD/Intel with Vulkan. Hardware test details.

git clone https://github.com/Rizzo-AI-Academy/rizzo-flow && cd rizzo-flow uv sync --locked uv run rizzo download # llama.cpp + 4B Q8_0, ~4.4 GB · --size 1.7b → ~1.8 GB uv run rizzo serve # → http://127.0.0.1:8017/playground